listenhub-hypit
Generate assets with ListenHub, then compose, align captions, and render locally with hypit.
Suggested prompts
About this skill
ListenHub Hypit
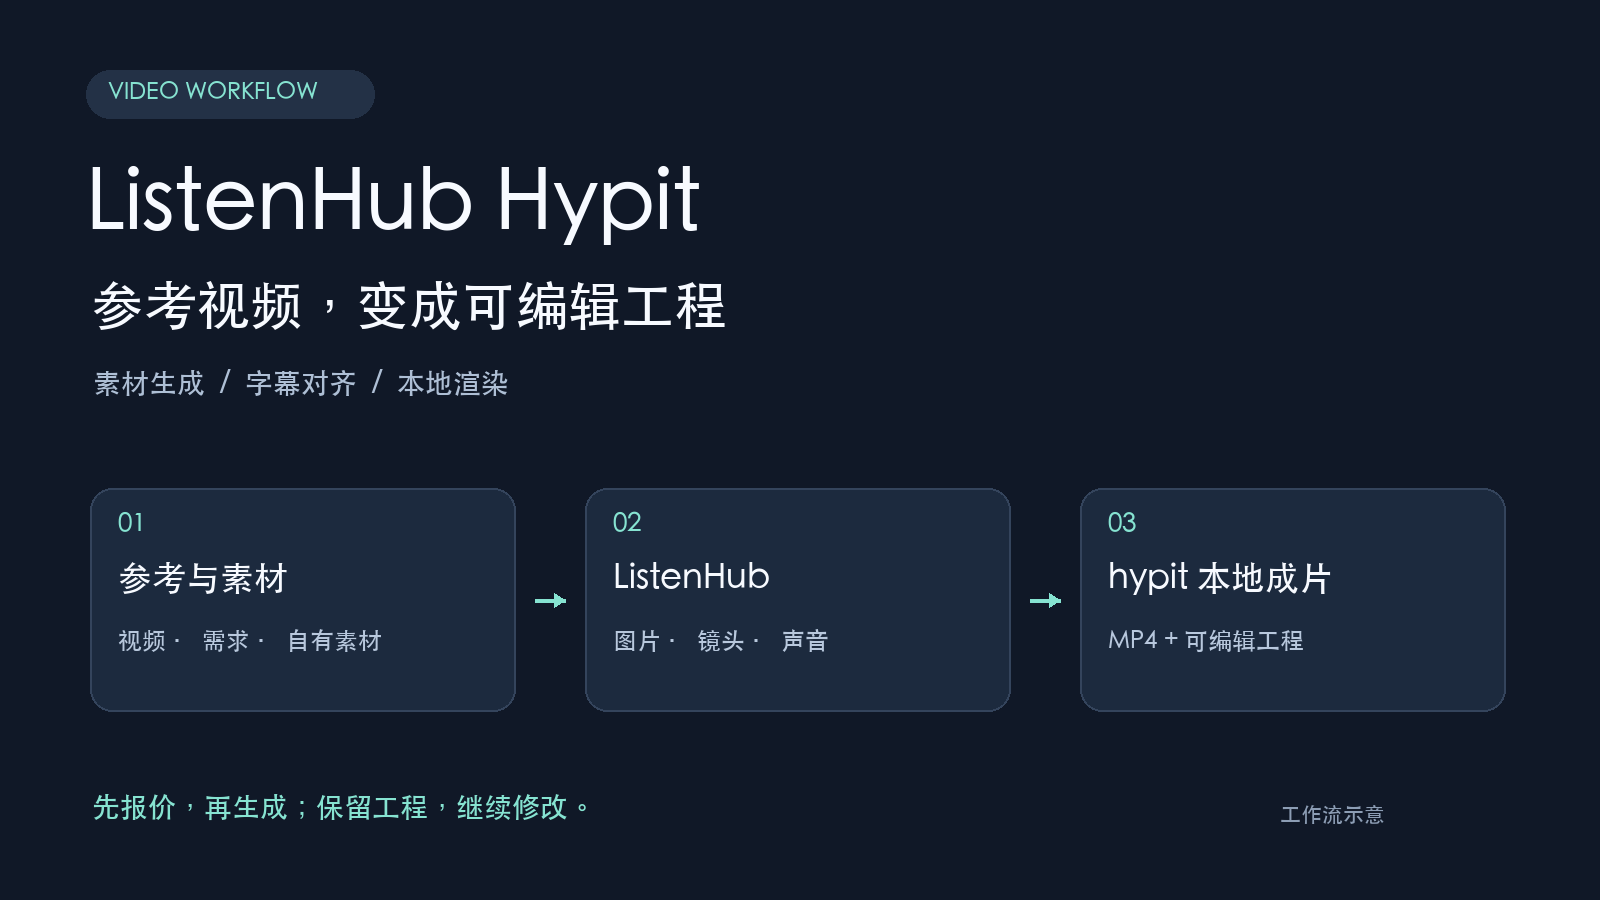
Turn a reference video, a creative brief, or your own assets into a video while keeping an editable hypit project. ListenHub generates images, video, voices, and music; hypit handles local composition, caption alignment, and rendering. The deliverables include an MP4 and project files.
Use cases
- Adapt a reference video by analyzing its shots, pacing, characters, and audio, then retaining or replacing elements as requested.
- Create character dialogue, talking pets, short dramas, podcasts, street interviews, and narrated demonstrations.
- Reuse existing footage, dialogue, or background music and generate missing assets.
- Change a line or segment in an existing project while reusing unchanged assets.
Core capabilities
- Route image, video, narration, voice cloning, and music generation according to the production needs.
- Produce word-level transcripts and align captions to the actual dialogue.
- Extract, trim, and mix existing audio locally; quote voice or music separation from mixed audio separately.
- Provide narration, dialogue, action, and still-image cutout templates, with dialogue and action in the same timeline.
- Retain project and segment records for further editing and rendering.
Workflow
- Supply a reference video, brief, or your own assets, including the number of outputs, duration, aspect ratio, language, and audio requirements.
- Analyze the reference and available assets, then identify what to reuse and generate.
- Review the itemized quote, pricing sources, and account balance before paid calls, and confirm the scope and budget.
- Generate missing assets, assemble the project, render locally, and inspect visuals, captions, and audio.
- Receive the MP4, the editable project location, and a reconciliation of estimated and actual credits.
Example request
Remake this clip with my product in it, keep the original background music, and swap the voiceover to English.
Requirements and costs
Requires a ListenHub API Key, Node.js 22.15 or later, npm, the ListenHub CLI, ffmpeg/ffprobe, uv, and a local hypit runtime. The workflow also calls companion ListenHub skills for images, video, narration, voice cloning, AI voices, and music; those separate skills are not included in this package. The agent follows the skill instructions to prepare the environment. No HypiHub account is required.
Cloud calls for generation, transcription, stem separation, voice cloning, and still-image cutouts are charged under ListenHub's pricing and quoted before execution. Reusing assets and extracting, trimming, mixing, or rendering locally do not consume generation credits. Assets requiring cloud processing are sent to the relevant ListenHub APIs.
Limitations
- Exact reproduction of arbitrary references is not guaranteed; inspect generated motion, voices, and lip synchronization.
- Separating voices or music from mixed audio can leave artifacts and reduce audio quality.
- Still-image cutouts redraw the subject against green before local keying, which can alter details. Green subjects and translucent materials are unsuitable.
- Audio-guided generation does not preserve the original waveform; check the resulting words, timing, and voice.
- Spoken text must match the project dialogue. Verify transcripts and captions.
- You must hold the appropriate rights to third-party audio.
- This skill and its bundled Provider use the MIT license. hypit is an external dependency with its own license; retain its branding and copyright notices and do not redistribute hypit as a hosted service or paid product.